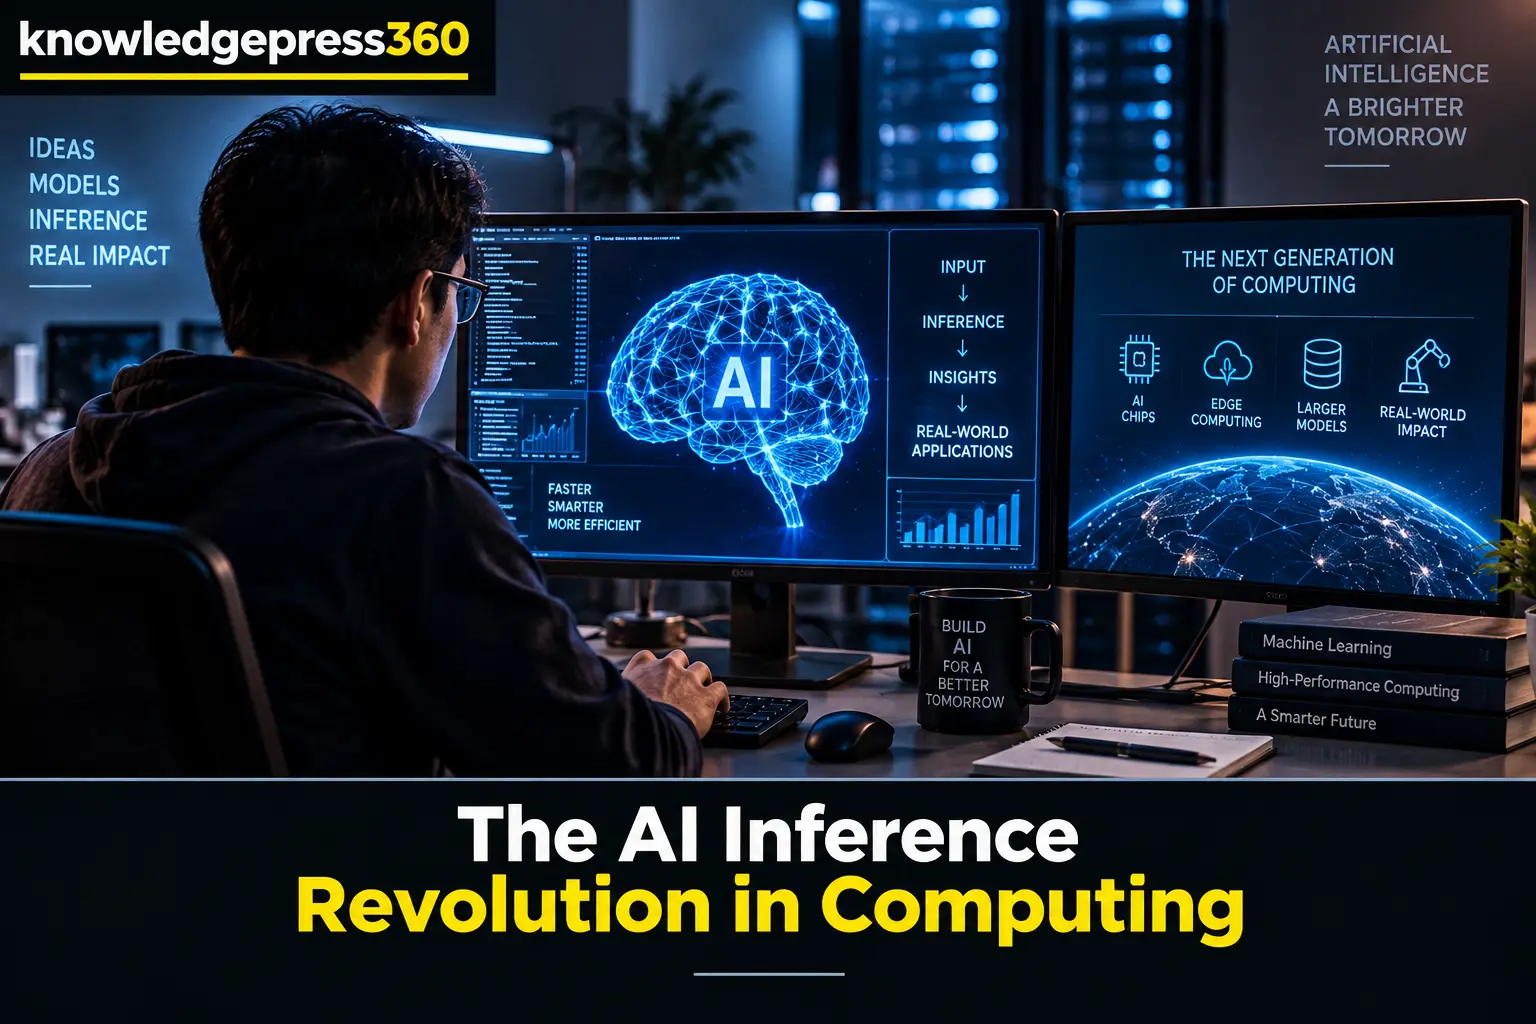
The computing and artificial intelligence sectors are undergoing a profound structural transformation, moving away from massive model training toward specialized inference infrastructure. For years, the technology industry focused primarily on building larger and more capable neural networks, scaling parameters from millions to trillions. While advanced laboratories continue to expand models, that phase has receded into the background of commercial strategy. Enterprise data centers now face an urgent imperative to deploy hardware capable of running deployed models efficiently at scale. This shift matters because everyday utility has skyrocketed, driving unprecedented demand for real-time processing power across global markets.
The Shift Toward Inference Infrastructure
By 2026, artificial intelligence inference has emerged as the central focus for enterprise data centers, supplanting model training as the primary commercial driver. Industry analysts describe this juncture as an inflection point where practical utility dictates hardware investments. Chief information officers across global enterprises are no longer focused solely on the immense computational cost of initial model creation. Instead, they demand architectures optimized for execution, deployment, and responsiveness. This pivot stems from tangible adoption rates, as large language models move from experimental novelties to indispensable daily tools across diverse industries. The sheer volume of daily interactions requires a completely re-engineered approach to silicon design and server cluster management.
Reasoning Models and Autonomous Agents
Underpinning this hardware pivot is a fundamental change in how artificial intelligence software behaves. Modern reasoning models no longer rely on a single computational pass to answer a prompt. Instead, they execute multiple internal evaluation steps through chain-of-thought processing, substantially increasing the computational load per user query. Furthermore, the rapid rise of agentic artificial intelligence means systems operate autonomously around the clock, executing tasks without direct human prompting. These continuous operational loops generate exponentially more text and computational demand than traditional reactive queries. Consequently, existing data-center configurations struggle to maintain adequate performance levels without triggering severe energy bottlenecks and latency constraints.
Custom Silicon and Strategic Alliances
To address these mounting operational pressures, major technology players are forging aggressive hardware alliances and designing custom silicon. OpenAI and Broadcom recently announced a dedicated application-specific integrated circuit named Jalapeño, engineered specifically for large language model inference at scale. Developed over a compressed nine-month timeline using insights from OpenAI operational roadmaps, this custom chip aims to deliver exceptional performance per watt compared to legacy hardware. Meanwhile, cloud providers are diversifying their infrastructure fleets by deploying alternative architectures, and industry leaders are snapping up specialized talent and intellectual property to secure a competitive advantage in the burgeoning inference market.